Millions of pages. Almost none of them readable. America's newspaper archives are scanned, free, and public domain — and effectively unusable. NewsPipe turns them into a publication you can actually read.
A digitised newspaper page arrives as one undifferentiated blob: unrelated stories run together, columns split mid-sentence, OCR that turns nineteenth-century type into gibberish. Existing archives hand you a keyword search over that mess. Nobody browses it, because there is nothing to browse.
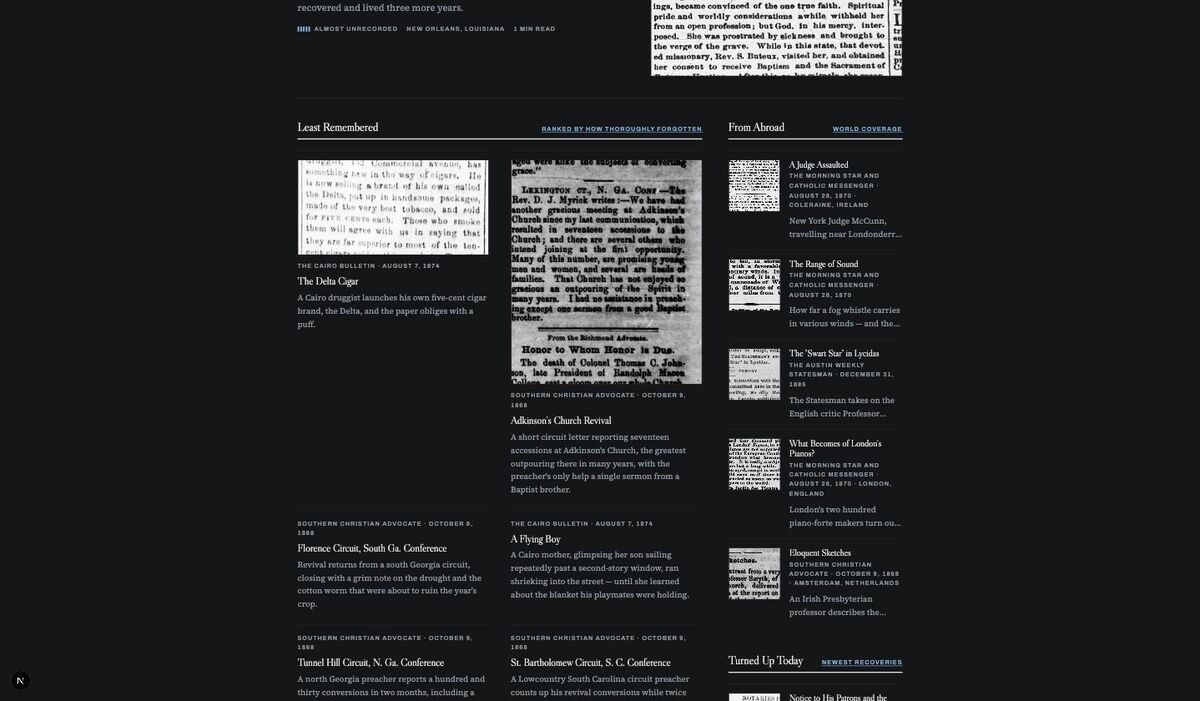
NewsPipe's core mechanic is one page in, many stories out. Each article is cut from the broadsheet and reassembled — headline, deck, byline, dateline, body — then restored without quietly improving the prose. Imagery comes from the scan itself: a cropped headline in hand-set display type, or a genuine engraving touching the story. Zero licensing, zero stock photos.
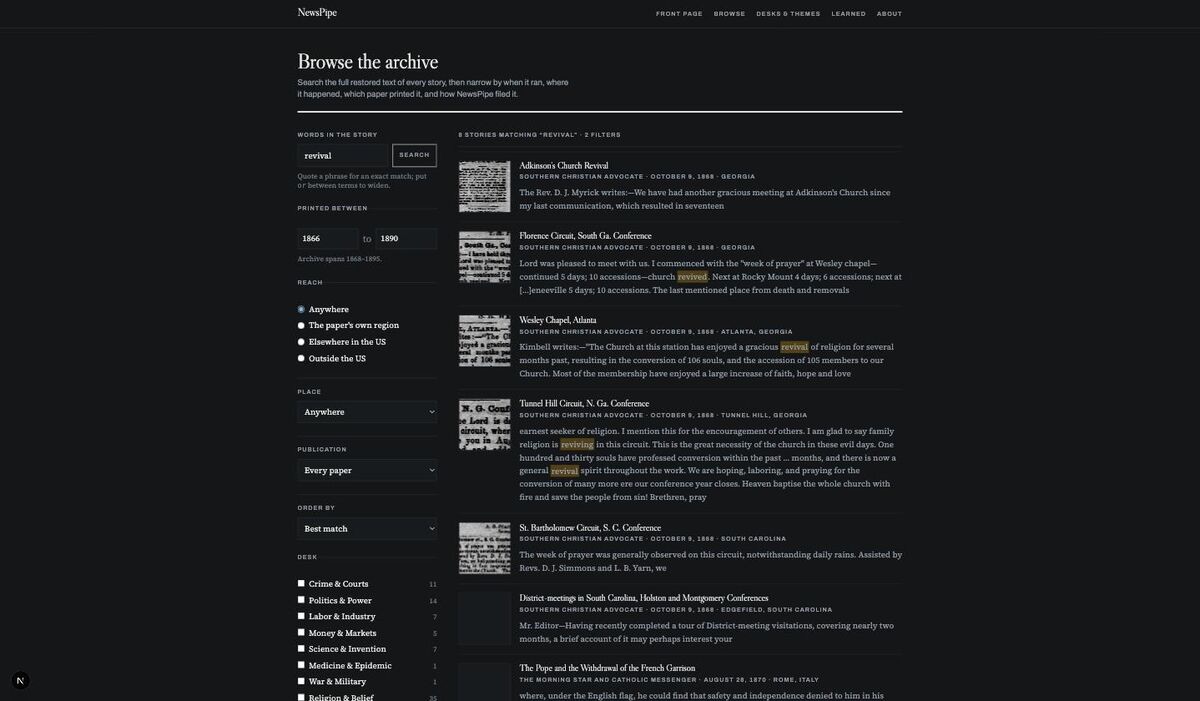
Readers get a front page ranked by what is forgotten, full-text browse with filters that live in the URL, and a reading view with editorial filing, named people, and a path back to the original scan. Restoration is a one-time cost per story; what it produces is a permanent structured asset. The archive only grows, and each day's edition is drawn from everything ever restored.
Live at newspipe.vercel.app.